
Top LiveBench score
LiveBench overall score82.4held by GPT 5.6 Sol Max
LMArena data, Rank.ai analysis
Behind the number
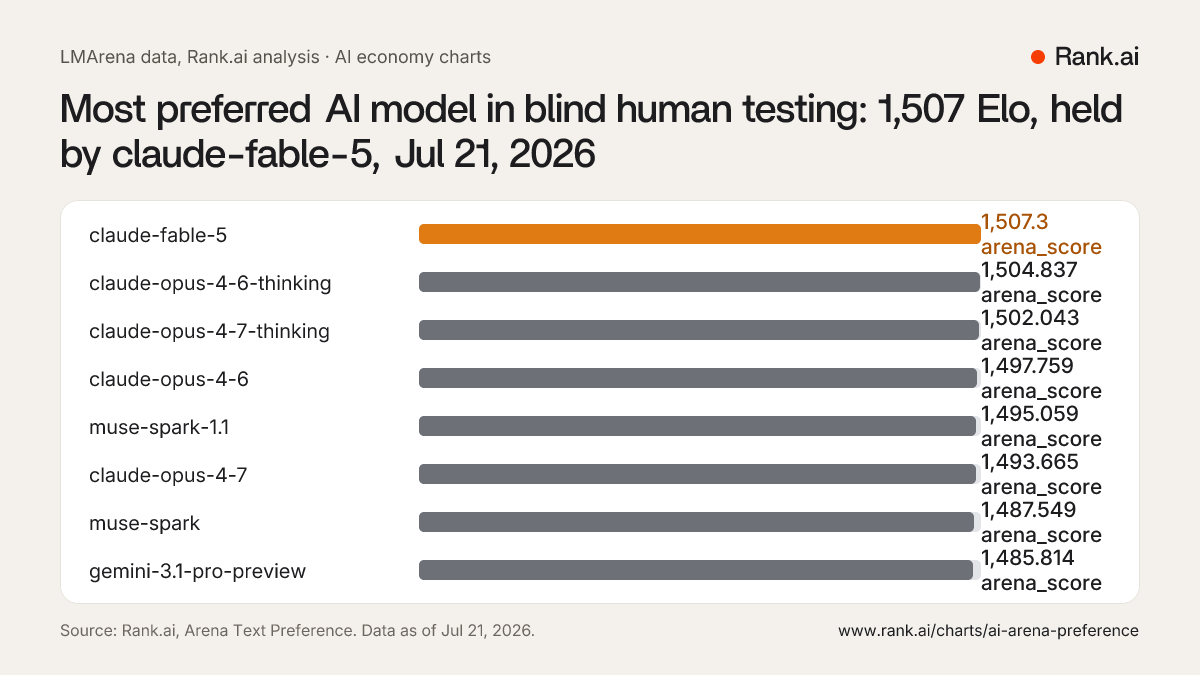
The board in rank order. The headline number is the top-ranked row, highlighted. Showing the top 12 of 378 ranked entries.
| Rank | Entry | Arena style-controlled Elo rating |
|---|---|---|
| 1 | claude-fable-5 | 1,507 Elo |
| 2 | claude-opus-4-6-thinking | 1,505 Elo |
| 3 | claude-opus-4-7-thinking | 1,502 Elo |
| 4 | claude-opus-4-6 | 1,498 Elo |
| 5 | muse-spark-1.1 | 1,495 Elo |
| 6 | claude-opus-4-7 | 1,494 Elo |
| 7 | muse-spark | 1,488 Elo |
| 8 | gemini-3.1-pro-preview | 1,486 Elo |
| 9 | gemini-3-pro | 1,486 Elo |
| 10 | kimi-k3 | 1,486 Elo |
| 11 | gpt-5.6-sol-xhigh | 1,485 Elo |
| 12 | gemini-3.6-flash | 1,485 Elo |
1,507 Elo on every publication so far. A line appears here as soon as the number moves.
Benchmarks measure what models can do; preference ratings measure what people actually choose. The Arena leaderboard collects blind head-to-head votes: a person asks a question, two anonymous models answer, and the person picks the better response. This chart tracks the top style-controlled text rating on that board, whichever model holds it.
Ratings are Elo scores computed from the full pairwise vote record, republished here from the official style-controlled text leaderboard, which corrects for formatting effects such as response length and markdown density. Elo is relative, so the number is only meaningful against the rest of the field, and a lead of a few points within the published confidence interval is a statistical tie.
Human preference often diverges from objective benchmarks: a model can lead on reasoning scores while losing blind votes on helpfulness and tone. When the same model tops both this line and the LiveBench line, the field has a clear leader; when they split, people are choosing between capability and style.
Charts
Enter your website. In about two minutes, Rank.ai asks ChatGPT, Claude and Gemini 12 questions your customers ask and grades how often they name you.