
OpenAI answer share
share of recommendation answers52.8%+5.6 pts
LiveBench data, Rank.ai analysis
Behind the number
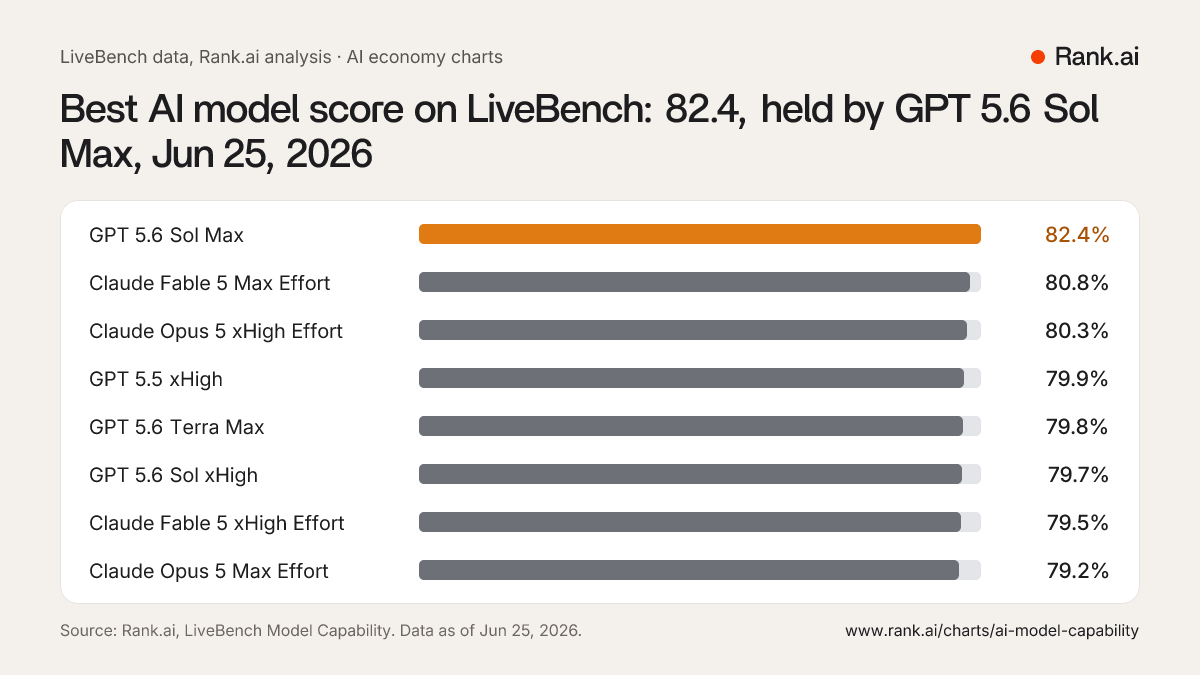
The board in rank order. The headline number is the top-ranked row, highlighted. Showing the top 12 of 45 ranked entries.
| Rank | Entry | LiveBench overall score |
|---|---|---|
| 1 | GPT 5.6 Sol Max | 82.4 |
| 2 | Claude Fable 5 Max Effort | 80.8 |
| 3 | Claude Opus 5 xHigh Effort | 80.3 |
| 4 | GPT 5.5 xHigh | 79.9 |
| 5 | GPT 5.6 Terra Max | 79.8 |
| 6 | GPT 5.6 Sol xHigh | 79.7 |
| 7 | Claude Fable 5 xHigh Effort | 79.5 |
| 8 | Claude Opus 5 Max Effort | 79.2 |
| 9 | Claude Opus 5 High Effort | 79.0 |
| 10 | Claude Opus 4 8 xHigh Effort | 78.9 |
| 11 | GPT 5.5 High | 78.7 |
| 12 | Kimi K3 | 78.5 |
82.4 on every publication so far. A line appears here as soon as the number moves.
LiveBench is an objective benchmark that scores exact model configurations across seven categories, including reasoning, coding, mathematics, and data analysis. Questions rotate to resist contamination, and grading is automatic rather than judged by other models. This chart tracks the single best overall score on the board, whichever configuration holds it.
The score is the unweighted mean of the seven LiveBench category averages for each official release, republished here per exact configuration rather than per marketing name. A model listed at high effort or maximum thinking budget is scored as that configuration only. The leader shown beside the number is read from the latest snapshot.
Vendor announcements lead with the evaluations they choose; a rotating, objective benchmark scores every model the same way. Watching the top score move, and which model holds it, is a simple way to follow capability between announcements.
Charts
Enter your website. In about two minutes, Rank.ai asks ChatGPT, Claude and Gemini 12 questions your customers ask and grades how often they name you.